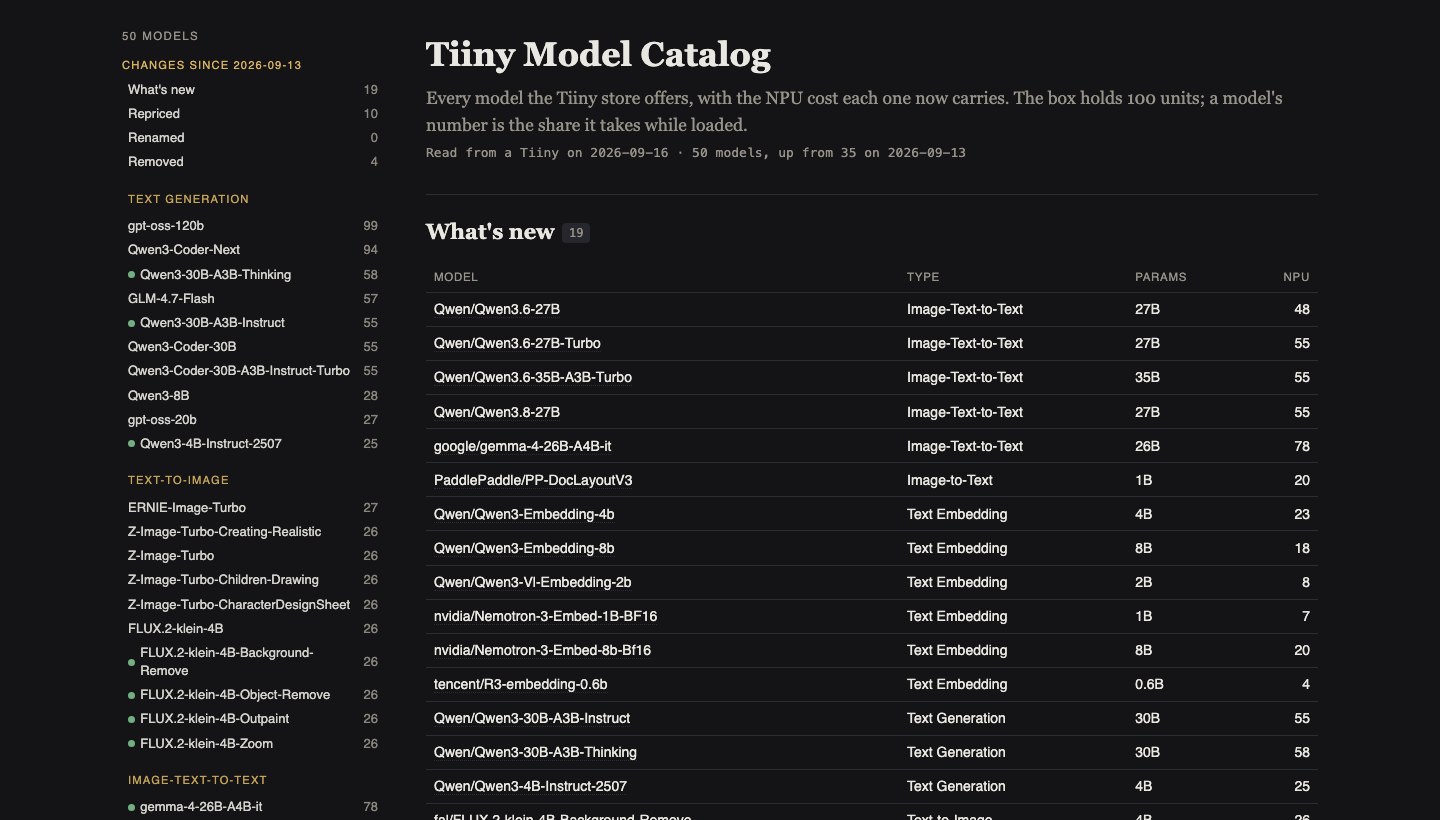
The store lists 50 models now, and the thing nobody says up front is that the number beside each one is a budget rather than a spec.
Your box has 100 NPU units. Everything you keep resident spends some: a 35B chat model is around 50, an image model around 32, a text-to-speech voice around 7, a small embedding model 1. They add up, and choosing what gets to sit in memory at the same time is most of the skill of running one of these.
Three things worth knowing before you go shopping:
A chat model and an embedding model is the pair most apps want, and it is cheap. That combination leaves plenty of room for something else.
Two big chat models will not co-reside. Pick one, and swap when you need the other.
A load that does not fit can fail quietly. The device will accept it and roll it back a moment later without saying so, so check what is actually running rather than trusting that the load worked.
The catalogue moves, so this page reads the store and leads with what changed: 19 models added, 10 repriced and 4 removed in the last sweep. It groups them by what they do and lists the unit cost of each.
https://artifacts.semfreak.dev/a/tiiny/models-94005402/
If you have found a combination that works well together, post it. That is the part no catalogue can tell you.
No comments yet.