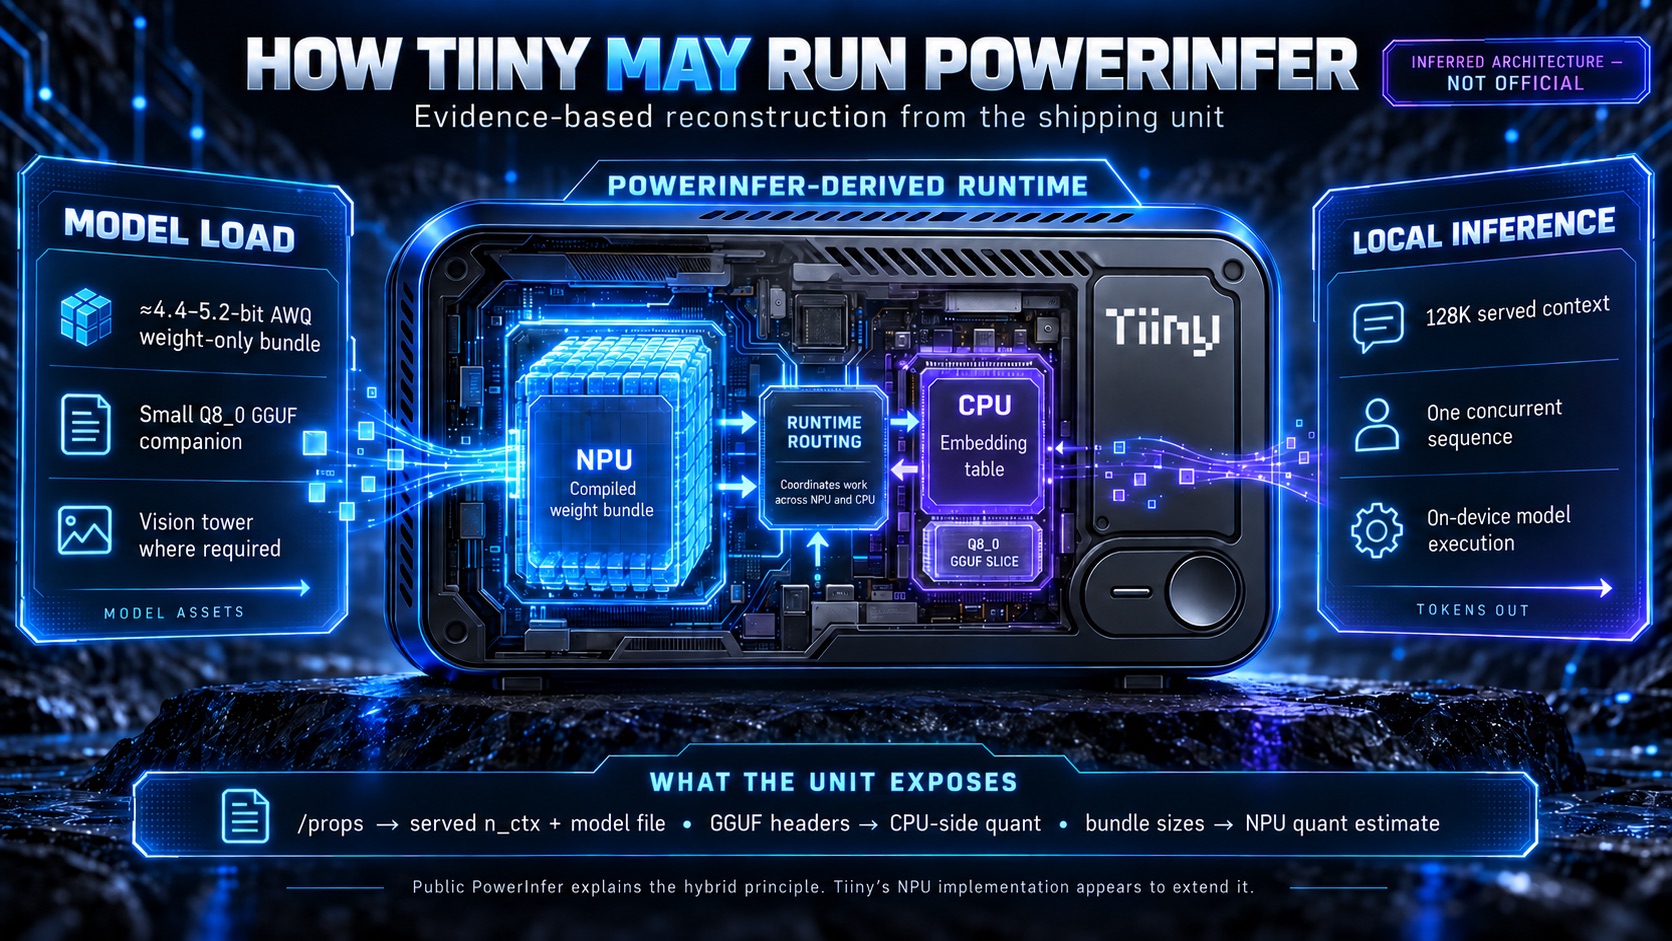
The short version is that almost none of the model runs on the CPU.
This was read off a unit rather than out of a doc. A chat model is served by a llama.cpp server, but the only weights sitting on the CPU side are the token embedding table. Every transformer layer and the output head run from a PowerInfer bundle compiled for the NPU ahead of time, and on the 27B and the turbo models there is a speculative draft model in there as well.
Three things that explain behaviour you have probably already run into:
The bundle is compiled at 131,072 context and one sequence. That is why the box takes one request at a time and a second caller gets error 150004. It is not a licence limit or a setting, it is how the graph was built.
The weights sit at roughly 4.4 to 5.2 bits each, near 4-bit AWQ with some parts kept at 8. A 35B model that would be about 70 GB in half precision takes around 18 GB on the box, so the size on the store page is what it costs you there and not what it would cost anywhere else.
The NPU does the work, so CPU load tells you almost nothing about whether the device is busy. Watch the NPU units instead.
The full reading is on this page, with what was measured on a unit kept separate from what the public repo says and what is inference on our part. It also gives the commands to read the same things off your own box.
https://artifacts.semfreak.dev/a/tiiny/hosting-71cb5df3/
If your unit reports something different, say so. That page changes when the facts do.
No comments yet.